Home Services AI Apps All Apps SEO Proof Ads Blog Contact

Production AI Mobile Apps.
Shipped in 3 Weeks.

Cross-platform iOS & Android mobile applications powered by streaming LLMs, vector memory (pgvector), and offline-first SQLite sync. Built and deployed by a senior product engineer with 4.1★ (489 reviews) on Google Play—without multi-month delays or bloated agency overhead.

Play Store 4.1★ (489 Reviews)
Live RAG System App (HmarAI)
Direct Senior Engineer (No Layers)
Fixed Sprints ($3,500–$7,500 MVP)
AI Mobile App Development by Divyaraj Kush: Flutter, iOS, Android, Firebase, Supabase
Verified AI Production Software

Featured Case Study: HmarAI Live AI Keyboard

Real technical evidence of deep mobile OS integration, streaming latency optimization, and personalized contextual AI memory.

Live AI Mobile App · Android System IME + RAG Memory

HmarAI — Smart System Keyboard & Contextual AI Assistant

Engineered a deep system-level Android Input Method Editor (IME) keyboard integrated with streaming LLM completions, contextual tone switching, and localized RAG memory. Built with custom Flutter settings, Kotlin native input service bindings, and local SQLite prompt caching.

< 320ms*
Time-to-First-Token
100%
Offline Keyboard Fallback
3 Tones
Instant Rephrase Engine
Native
Kotlin + Flutter Channel

*Measured in local test environment; actual network latency varies by carrier network, model provider, geographic region, and prompt context length.
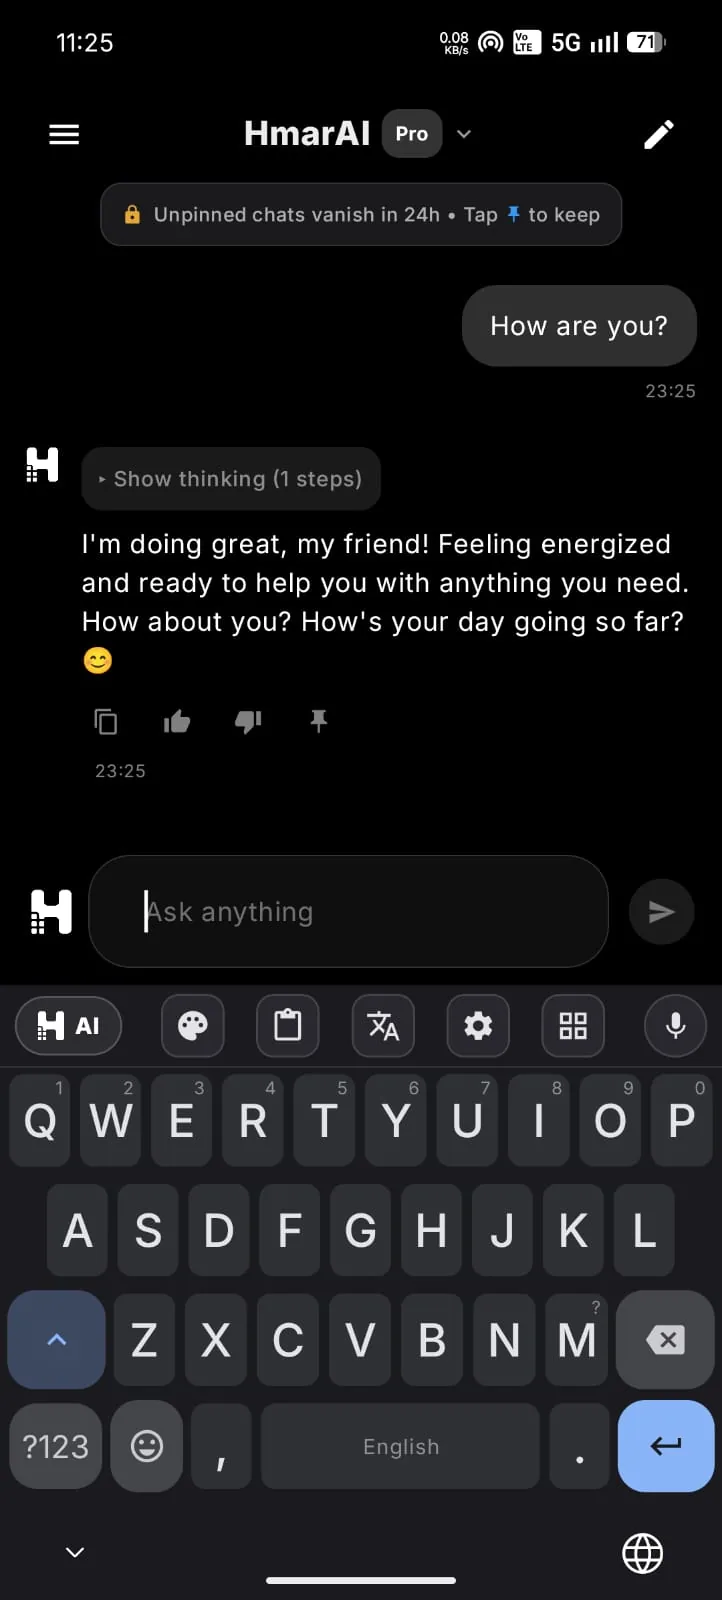
HmarAI Chat & Streaming Assistant
Sub-second Streaming Chat & Memory
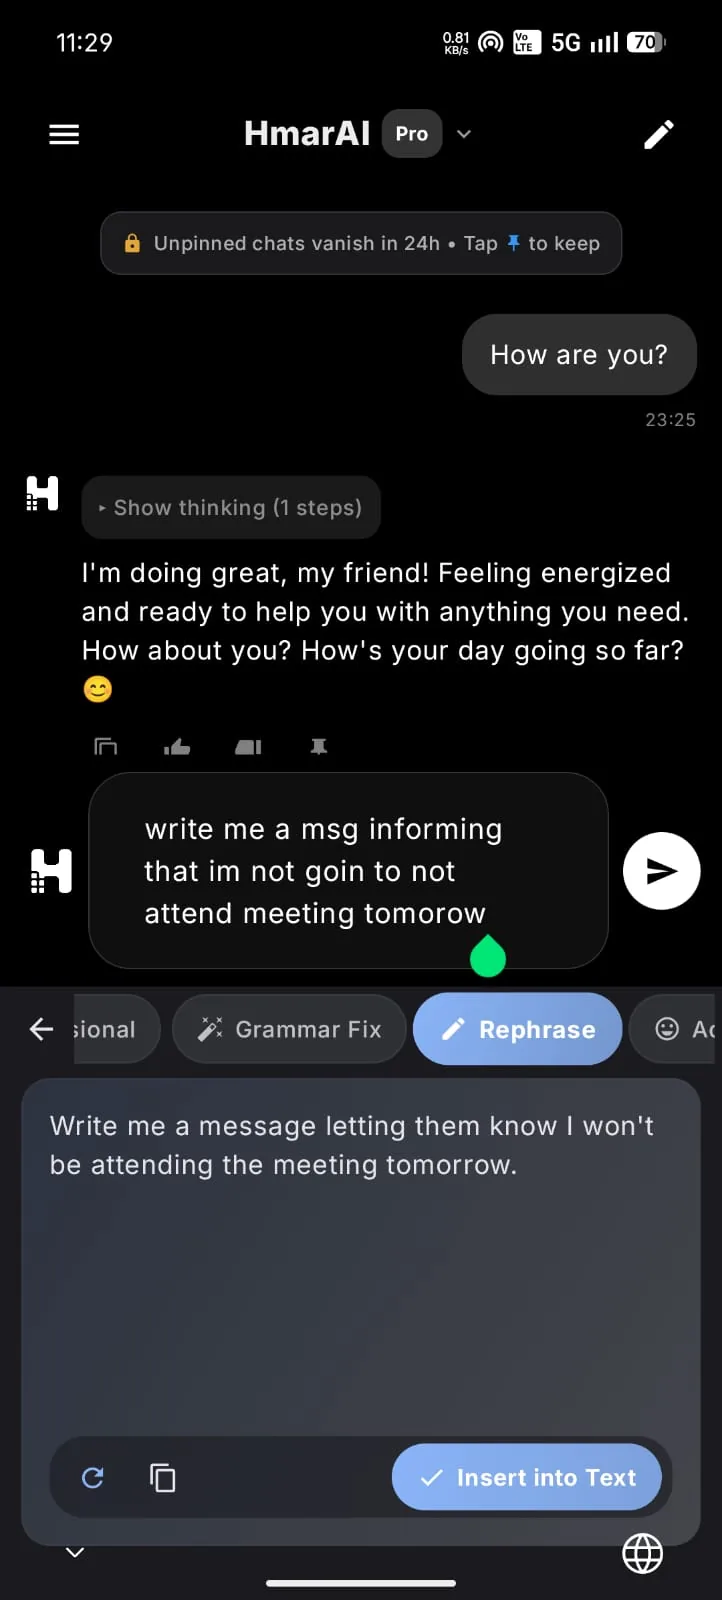
HmarAI System Keyboard Rephrase
System Keyboard Real-Time Rephrase
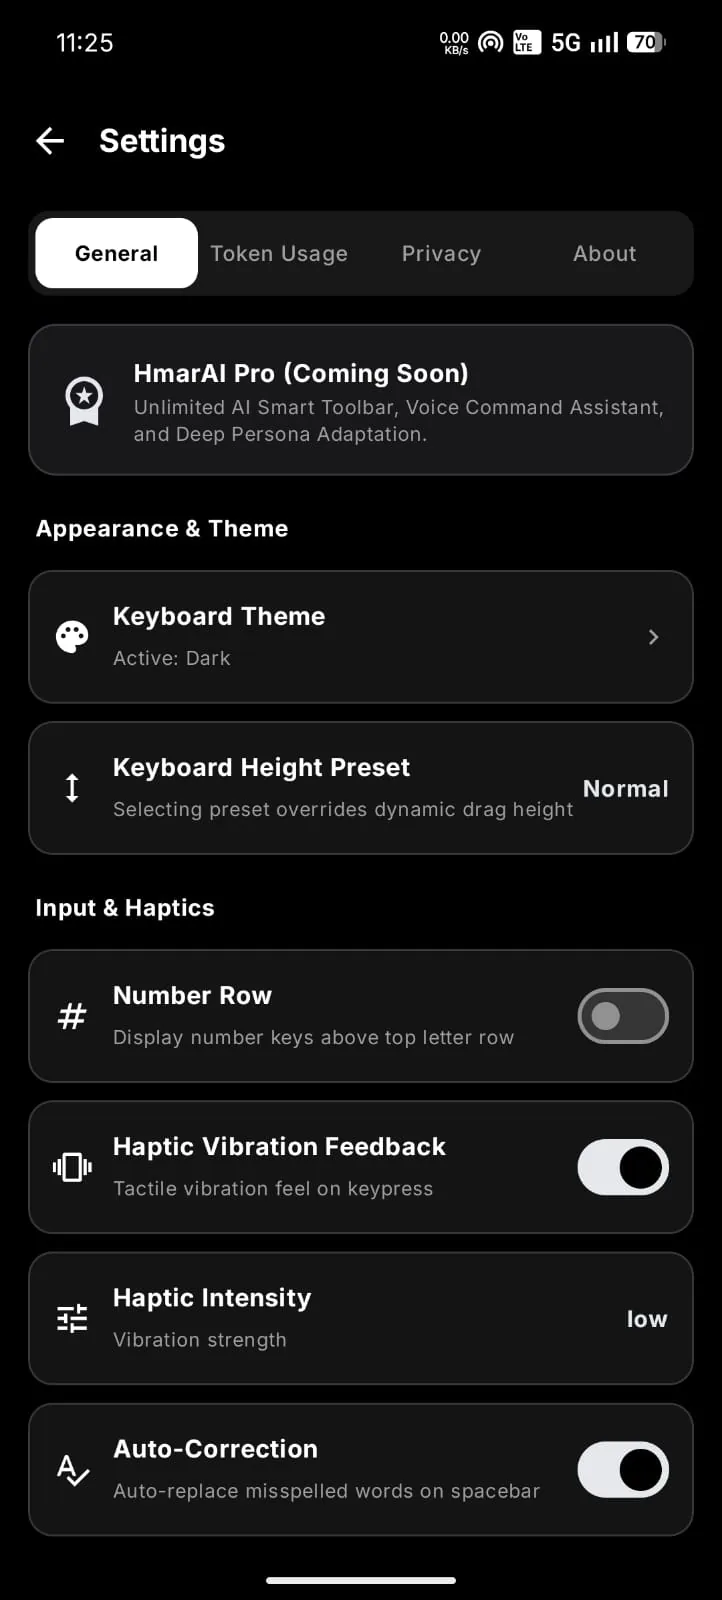
HmarAI Settings & Theme Config
Theme & Haptic Engine Configuration
Engineering Standards

How I Architect Production-Grade AI Apps

Built on battle-tested architectural principles to ensure lightning-fast UI responsiveness, minimal token expenditure, and bulletproof security.

// 01 — CROSS-PLATFORM MOBILE ENGINE

Flutter (iOS + Android + Web)

A single Dart codebase compiled to native machine code, with Flutter’s modern Impeller rendering engine handling GPU rendering across iOS and Android. A consistent cross-platform stack with direct native platform channels for camera, microphone, haptics, and background sync.

Flutter 3.xDart NativeImpeller GPUiOS + AndroidPlatform Channels
// 02 — STREAMING & TOKEN EFFICIENCY

Sub-400ms Time-to-First-Token

Server-Sent Events (SSE) stream tokens directly into reactive Flutter state with instant optimistic rendering. Dynamic prompt caching cuts repeat token costs by up to 80%. Dynamic model routing balances low-latency high-frequency tasks and deep multi-step reasoning across frontier providers.

SSE StreamingPrompt CachingOpenAI APIsAnthropic APIsGemini APIsModel Routing
// 03 — VECTOR SEARCH & OFFLINE DATA

Hybrid RAG + Offline SQLite

Offline-first SQLite caching ensures instant UI loads even on flaky 3G or airplane mode. Cloud vector embeddings via Supabase pgvector deliver contextual document retrieval and conversational memory at near-zero latency.

Supabase pgvectorSQLite / DriftOffline-FirstRAG MemoryText Embeddings
// 04 — SECURITY & STORE COMPLIANCE

Hardened Token Proxy & Compliance

Zero API keys in client-side code. All calls pass through secure backend Edge Functions with user authentication, Redis rate limiting, abuse protection, and Apple Guideline 4.2 / Google Play generative AI safety compliance built in.

Edge ProxyJWT AuthRate LimitingStore ComplianceIP Whitelisting
Reality Check

Why Startup AI Apps Often Stumble Before Launch

Most mobile AI failures are not model limitations—they are caused by flawed engineering decisions early in development.

// 01 — OVERBUILT PROCESS

The Bloated Agency Overhead

Agencies often quote $70k–$150k and 6-month timelines. Sizable budget shares get absorbed by account management layers, decks, and teams learning mobile AI architectures on your dime.

// 02 — WEAK ARCHITECTURE

The Unprotected Client-Side Wrapper

Sloppy implementations expose raw LLM API keys directly inside mobile binaries, leading to token theft. Without native utility, Apple can reject apps under its Minimum Functionality guidelines (Guideline 4.2).

// 03 — COST & LATENCY TRAPS

The Multi-Second Latency Freeze

Waiting 5+ seconds for an LLM JSON payload destroys mobile user retention. Production AI apps require Server-Sent Events (SSE) streaming tokens straight to 60 FPS UI widgets with prompt caching and strict per-user rate limits.

Proven Engineering Track Record

High-Scale Production Proof: Rank Dangal

Demonstrating full-cycle product engineering across real users and store environments—not just isolated API wrapper prototypes.

Live on Google Play · 4.1★ (489 Reviews) · #1 Google SERP

Rank Dangal — High-Scale Cross-Platform Quiz & EdTech Engine

Shipped Flutter mobile app and web app (rankdangal.web.app). Handles hundreds of concurrent interactive sessions with Firebase Cloud Sync, offline state persistence, and sub-50ms question transitions. Ranks #1 on Google SERP with an active AI Overview citation.

4.1 ★
489 Play Store Reviews
13.9k
90-Day GSC Impressions
#1
Google Rank + AI Cited
sub-50ms*
Question Transition

*Measured app-state transition time in production benchmark testing.

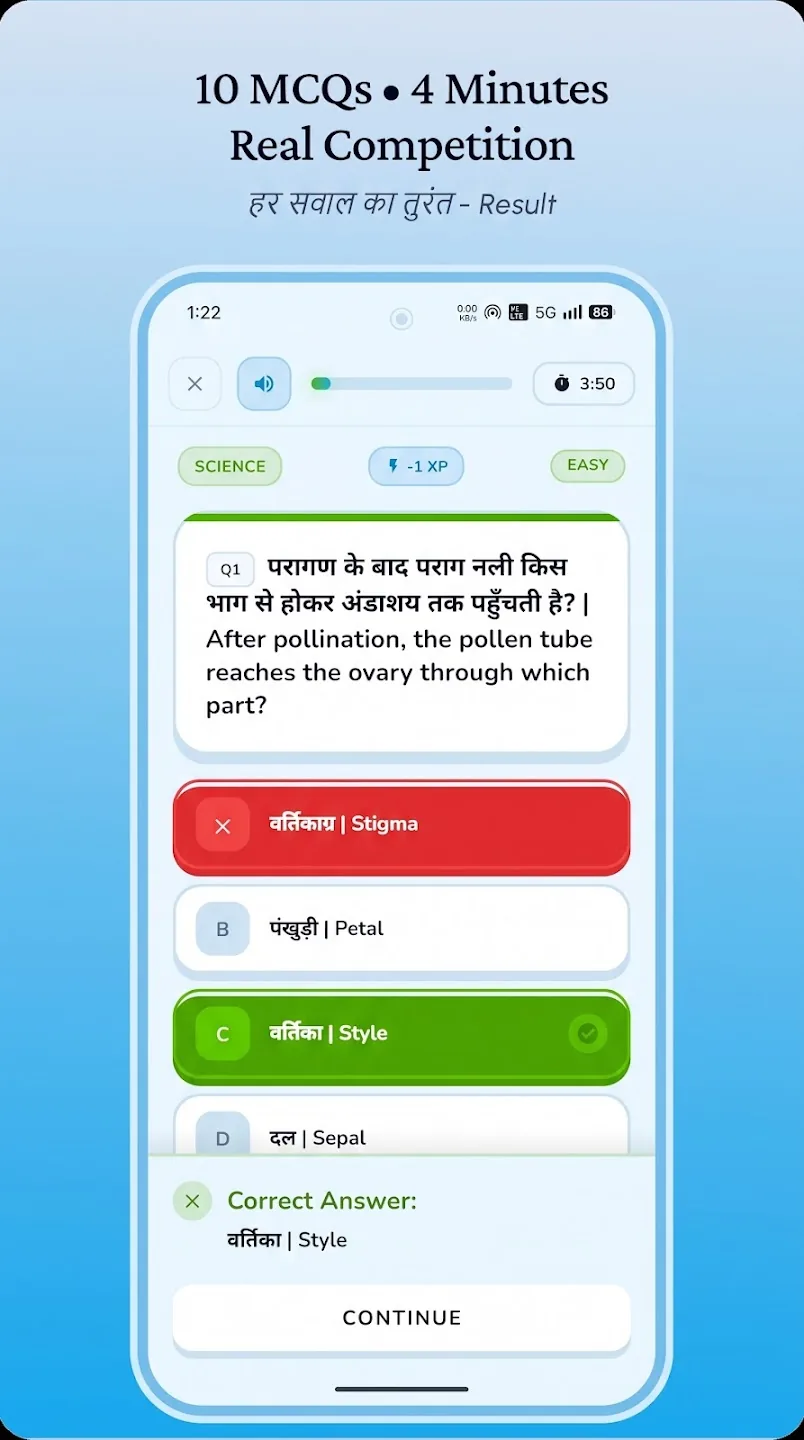
Rank Dangal Live Quiz UI
Sub-50ms Question Transition State
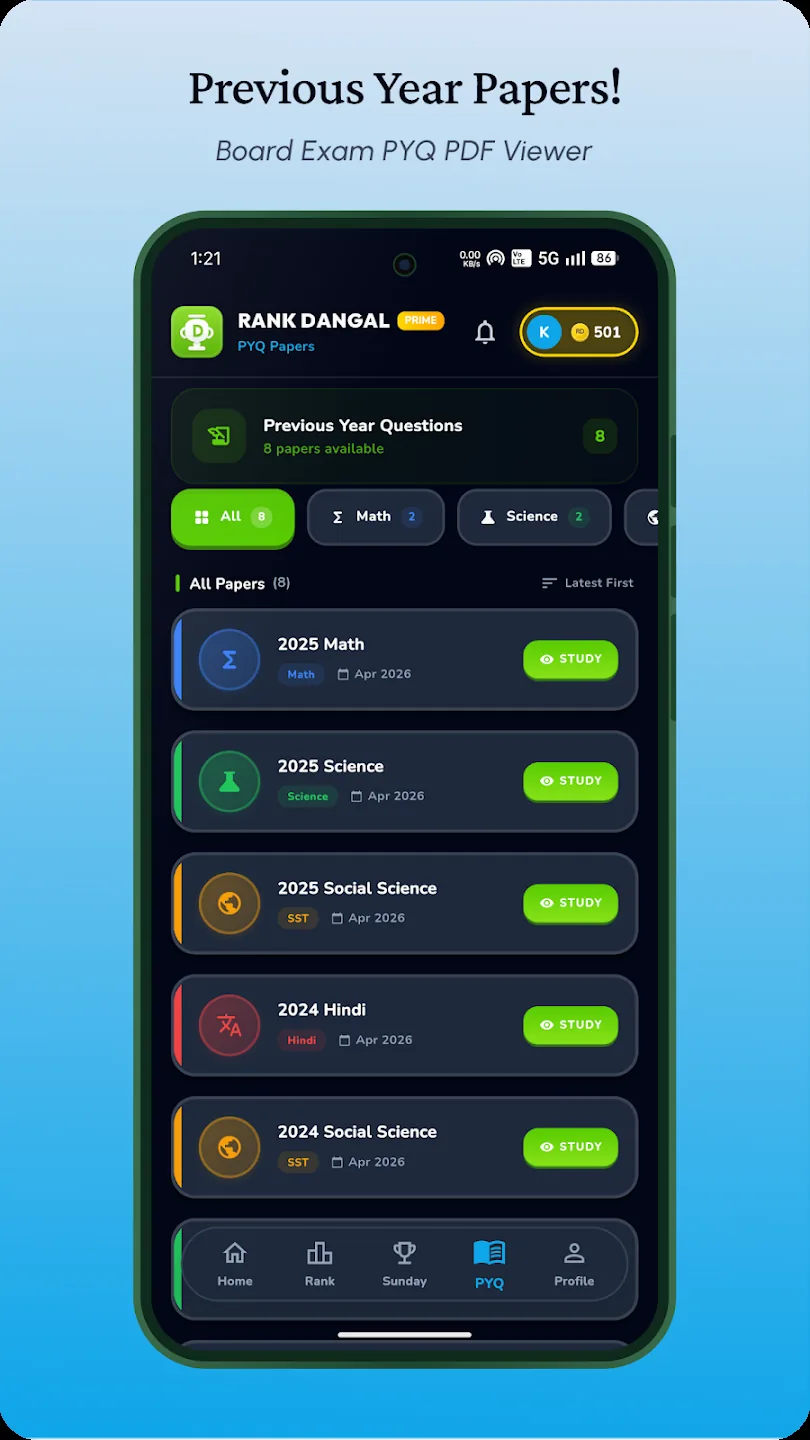
Rank Dangal Dark UI
High-Contrast Dark Mode Architecture
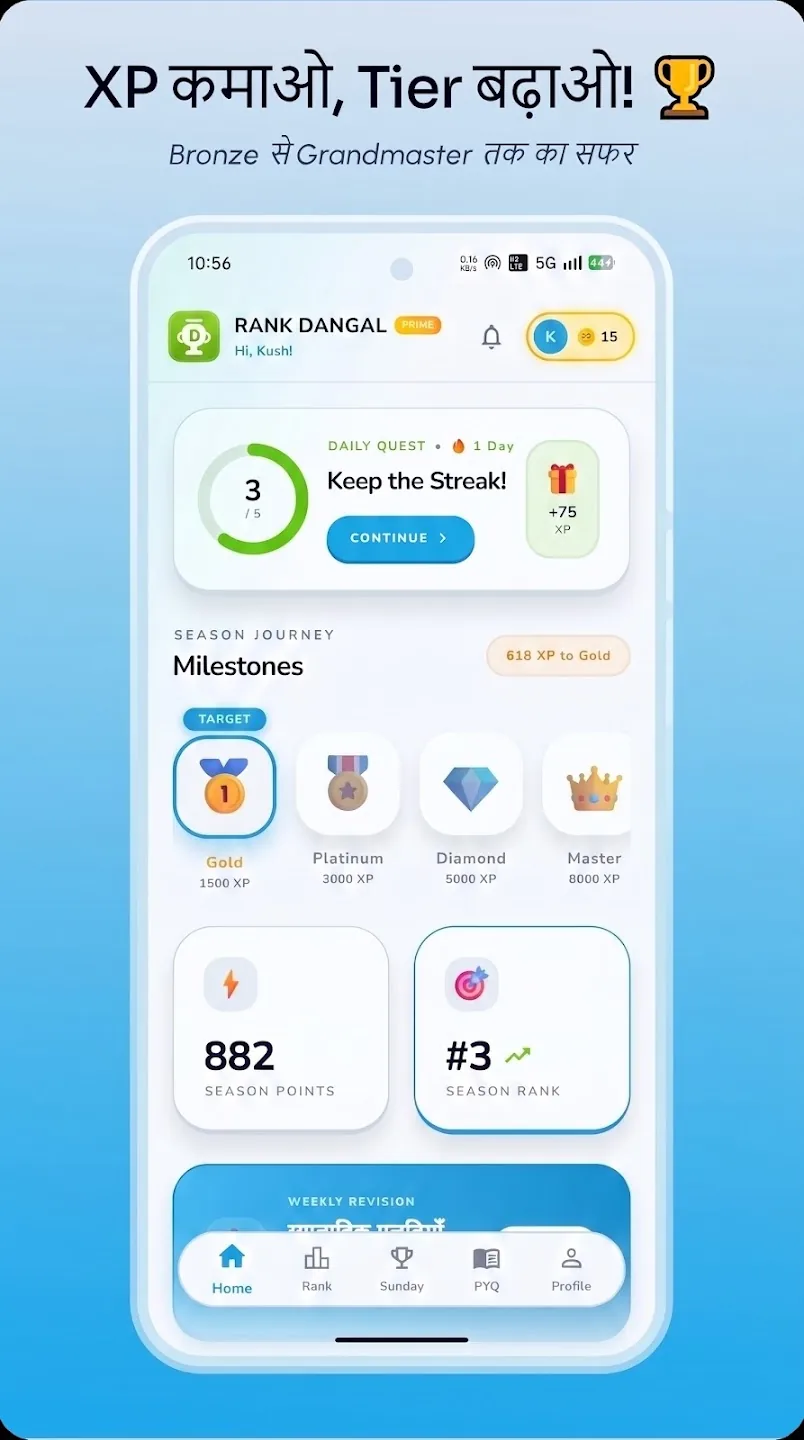
Rank Dangal XP Gamification
Real-Time XP Leaderboards & State
Decision Framework

Why AI Development Quotes Vary

An objective look at how working with a dedicated senior product engineer compares with agency models and marketplace freelancers.

Evaluation Dimension Divyaraj (Senior Product Engineer) Traditional Dev Agency Marketplace Freelancers
Communication Direct with the engineer writing code Account reps, project managers, handoffs Disconnected, communication friction
Architecture Single holistic owner (Flutter + SQLite + pgvector) Fragmented across separate frontend/backend roles Often copied templates, unvetted architecture
Scope & Velocity 2 to 4-week fixed-scope sprint 4 to 7-month open-ended contracts Task-based, unpredictable rework
Cost Structure $3,500 – $9,500 fixed scope (zero agency overhead) $70,000 – $150,000+ (substantial agency margin) Low entry price ($500–$2k), high risk of rewrite
Token Cost Guardrails Prompt caching, SSE streaming, model routing Rarely optimized, costly API bills passed to client Uncached client calls, runaway billing risk
Store Review Preparation Compliance preparation & rejection-response support Handled, but adds weeks of administrative overhead Leaves you to deal with platform rejections
IP & Source Code 100% transfer on milestone completion May retain proprietary modules or ongoing lock-in Uncertain licensing and unverified dependencies
Predictable Investment

Fixed-Scope AI Mobile App Sprints

No open-ended billing or surprise invoices. Clear milestone deliverables with daily Loom updates, direct communication, and full code ownership.

AI Mobile MVP
For seed-stage founders validating an AI mobile product with real early adopters.
$3,500 – $5,000
2–3 Week Rapid Sprint
  • Cross-platform Flutter app (iOS & Android)
  • Core streaming AI feature (Chat / Assistant / Voice)
  • Supabase / Firebase Auth & Database
  • Secure backend token proxy (No exposed keys)
  • Sub-400ms Time-to-First-Token SSE streaming
  • TestFlight & Play Store Internal Track deployment
Select MVP Sprint
Fractional AI Product Engineer
For funded teams requiring high-velocity sprint capacity and continuous AI product iteration.
$3,500/mo
Monthly Retainer (Cancel Anytime)
  • Dedicated weekly development sprint capacity
  • New feature architecture, model eval & testing
  • Direct integration into your Slack/Discord
  • Daily EST/PST overlap for live sync calls
  • Code reviews, CI/CD maintenance, store updates
Inquire for Retainer
The Roadmap

From Concept to App Stores in 4 Disciplined Steps

A transparent, low-overhead process designed to get working software onto test devices quickly.

01

Architectural Discovery

30-minute scope lock. We define your data models, user flows, LLM provider strategy (dynamic model routing across Anthropic, Gemini, OpenAI), and milestone deliverables.

02

Interactive Prototype

Days 3–5: Clickable Flutter prototype running on your device via TestFlight or APK. Validates UI ergonomics and latency benchmarks early.

03

Production Build Sprint

Days 6–18: Core engineering—token streaming, vector indexing, offline sync, auth, and in-app purchases. Daily asynchronous Loom updates.

04

Security Audit & Launch

Days 19–21: Security audit, Apple Guideline 4.2 compliance preparation, App Store & Google Play submission support, and 100% IP handover.

FAQ

Technical & Commercial Questions

Why choose Flutter over React Native for AI mobile apps?

Flutter compiles Dart directly to native machine code and renders via the Impeller GPU engine at a smooth 60–120 FPS. When streaming LLM tokens, frequent reactive UI updates must remain fluid without frame drops. Flutter provides unified cross-platform state management and direct native integrations (such as HmarAI's Android system IME keyboard service) while sharing 100% of business logic across iOS and Android.

How do you prevent users from running up huge API bills?

We implement a 4-tier cost shield: (1) System prompt caching which reduces repeat input token billing by up to 80%; (2) Semantic response caching with local SQLite and Redis to instantly return repeated user queries; (3) Dynamic model routing where high-frequency tasks route to low-latency models and complex multi-step reasoning routes to frontier models; and (4) Strict per-user rate limiting.

What happens if Apple or Google rejects the app?

I provide comprehensive App Store & Google Play compliance preparation and rejection-response support for our agreed sprint scope. Apple requires clear user reporting mechanisms for AI-generated content, terms of service agreements, and minimum functionality standards (Guideline 4.2). I prepare all submission materials against current platform requirements, then personally handle the review cycle and resolve rejection feedback where needed.

Do I own the source code and intellectual property?

Yes. 100% of all Flutter frontend code, backend cloud functions, database schemas, prompt templates, and deployment scripts transfer entirely to your GitHub organization upon milestone completion. No licensing fees, no proprietary lock-in.

How do we handle communication and time zones?

I operate with dedicated daily 3–4 hour overlap with US Eastern (EST) and Pacific (PST) business hours. Communication happens asynchronously on Slack or Discord with daily video/text loom progress updates, GitHub PR visibility, and scheduled weekly milestone reviews.

Start an AI Mobile App Project Brief
Direct review by Divyaraj. I respond within 24 hours with architectural considerations, preliminary scope, and transparent milestone pricing (EST & PST friendly).
Your details stay private. No spam. Direct response from Divyaraj within 24 hours.

AI Project Brief Received!

Thank you! I will review your requirements and reach out to your email within 24 hours with an architectural plan and preliminary sprint timeline.

Direct Email: hello@divyaraj.dev

Or Reach Out Directly

Email
WhatsApp
LinkedIn
X (Twitter)